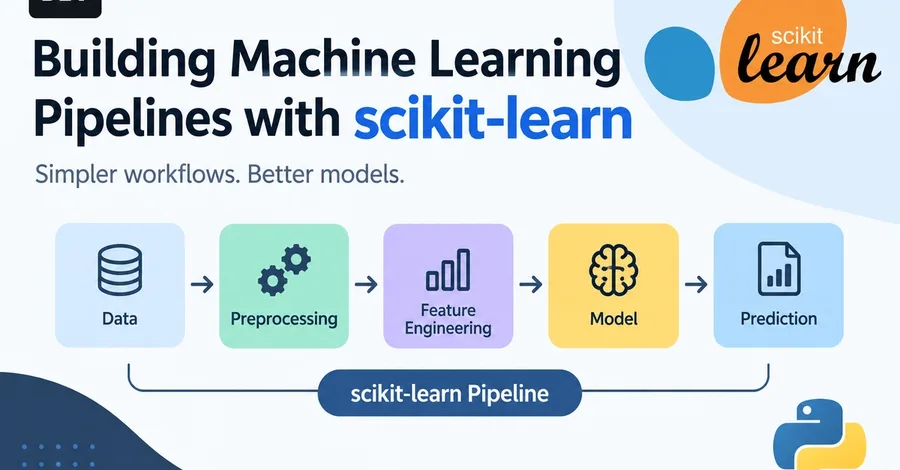
Introduction: Datasets usually contain errors, making them messy and unsuitable for analysis or manipulation. This means data preprocessing must be conducted, i.e cleaning, scaling, and encoding of your numerical and categorical columns iteratively for each batch of data you process before you can analyse or make predictions. Doing this manually is tedious and error-prone. This is where scikit-le…
Plant point cloud segmentation is emerging as a critical tool in modern crop breeding, where the ability to analyze plant organs with high precision enables breeders to quantify traits that influence yield, resilience, and resource efficiency. Tradit
The reliability of global food systems depends on precise, scalable monitoring of agricultural landscapes, but traditional methods struggle to keep pace with the complexity of modern farming. As climate change intensifies and arable land becomes more
LONDON, UK — Orchestra, the Agentic Control Plane for enterprise data and AI workflows, today announced its formal launch following a year in which platform usage grew more than 10x. Backed by $4.6 million in funding to date, the AI-native platform brings pipelines and governed AI agents into one environment, giving data teams greater control... … continue reading The post Orchestra Launches Agen…
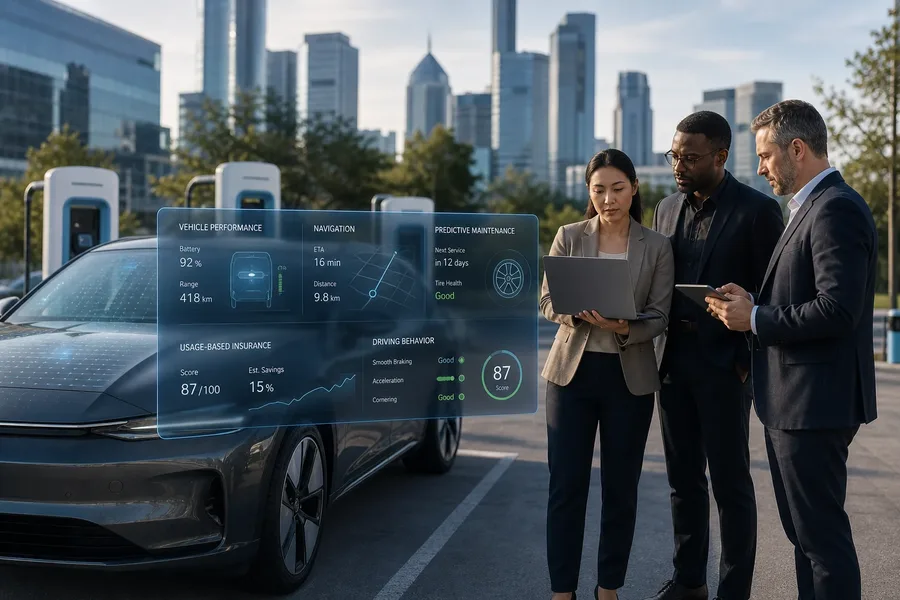
Why Automotive Data Monetization Matters Now The automotive industry has become one of the most data-intensive sectors in the global economy. Modern connected vehicles continuously generate telematics, location, performance, battery, and driver behavior data. Organizations that can turn these signals into actionable insights are creating new revenue streams across the mobility ecosystem.
Redfin has named former Meta executive Alessio Sanfilippo as CEO, succeeding Rocket CEO Varun Krishna, who had run the company since Glenn Kelman's departure in January. Sanfilippo previously led data and insights at Meta's Reality Labs and WhatsApp. The move follows Rocket's $1.75 billion acquisition of Redfin last year. Read More
Introduction Microsoft Excel is the most popular tool for data work and analysis. Its user-friendly environment makes it easy to understand, organize, clean, and explore data. For a data analyst or scientist, knowing how to work with Excel goes beyond entering information into cells. Excel can be used to inspect datasets, identify errors, standardize values, filter records, sort information, remo…
This article introduces the evolution of an open standard designed to help enterprise data and AI tools interpret the same business metrics consistently.
Bibliometrics is increasingly being used by the knowledge community and librarians to easily analyze patterns in knowledge. In the field, the use of data from databases that provide bibliometric information is not always completely clean, so pre-processing is required. Several previous studies have shown that bibliometric analysis begins with a simple pre-processing step. The goal of this researc…
As AI research continue to accelerate, many Statistics and biostatistics faculty members are eager to explore new more data-intensive research directions. Recently, a new resource for the statistics and biostatistics community was launched: A comprehensive biomedical data resource guide, available at here. This platform serves as a curated collection of links to diverse biomedical datasets, enabl…
The benefits of having data Two ways to look at drive failures and temperature. Almost all recent articles and papers I have read on hard drive failure rates refer to either Failure Trends in a Large Disk Drive Population from Google, or Estimating Drive Reliability in Desktop Computers and Consumer Electronics Systems from Seagate. Despite both sounding and looking authoritative, these papers co…
The digitization of healthcare has led to an unprecedented growth in health-related data, offering new opportunities to transform clinical decision-making, disease prediction, and patient engagement. However, extracting actionable insights from diverse data sources such as electronic health records, wearable devices, and mobile health apps requires a fusion of domain knowledge in healthcare and t…
When preparing for DP-750: Microsoft Certified: Azure Databricks Data Engineer Associate , you need to understand two related but different topics: Slowly Changing Dimensions , SCD Data quality expectations in Lakeflow Spark Declarative Pipelines SCD is about how to model changes in dimension data over time. Data quality expectations are about validating records as they flow through a pipeline. T…

 research.io