How model validation standards are changing for LLM-based systems: what breaks, what carries over, and how to test output quality The post The Model Validation Playbook for GenAI: Lessons from Banking appeared first on Towards Data Science .
A context window can be technically complete and still describe a world that no longer exists. I built a deterministic benchmark to measure the cost of acting on stale context. The post Context Windows Don’t Know What’s Still True — I Built a Validity Layer That Does appeared first on Towards Data Science .
I saved my day with a mere $52 bill. But you don't have to repeat my mistake. The post I Vibe-Coded an App in Just Two Hours (And Regretted It the Next Day) appeared first on Towards Data Science .
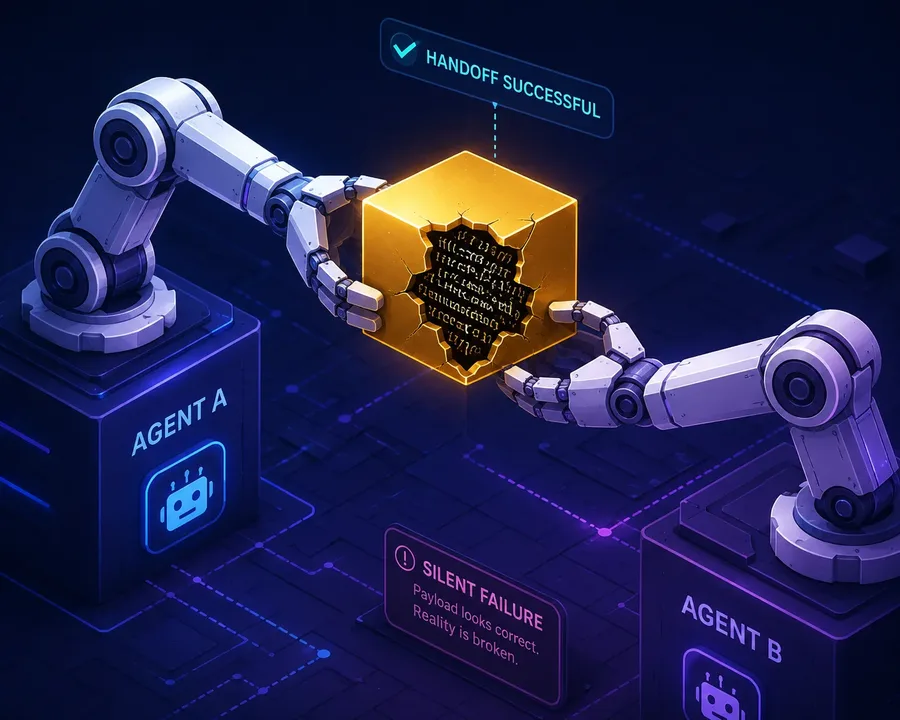
How to catch a payload that looks correct but isn't, using a watchdog pattern with working Python. The post Why Most Multi-Agent Systems Fail Even When Evaluation Passes appeared first on Towards Data Science .
AI companies quietly watermark billions of words a day. Here’s how to apply the same three families of techniques to your own writing—and what real experiments reveal about which watermarks survive copy-paste, editing, and paraphrasing. The post Text Watermarking in Python: Catch Whoever Copies Your Writing appeared first on Towards Data Science .
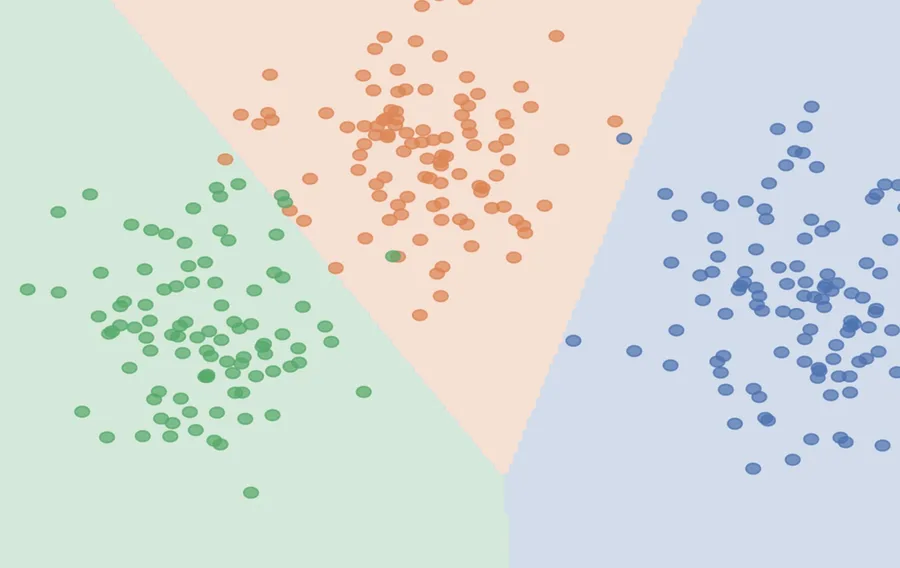
Using LDA for dimensionality reduction in classification problems The post Linear Discriminant Analysis (LDA) in Real-Life: Dimensionality Reduction in a Real-Estate Dataset appeared first on Towards Data Science .
From scalar observations to self-attention, and how positional information restores sequence order The post Why Transformers Need Positional Encoding For Time Series: A Visual Guide appeared first on Towards Data Science .
Improving reinforcement learning for complex physics The post Dynamical System Transfer Learning with Reduced Order Models appeared first on Towards Data Science .
Why the default 50/50 split is the wrong move when your treatment is more expensive than your control, and how cost-based sampling weights fix it The post Optimal Traffic Allocation Under Heterogeneous Variant Cost appeared first on Towards Data Science .
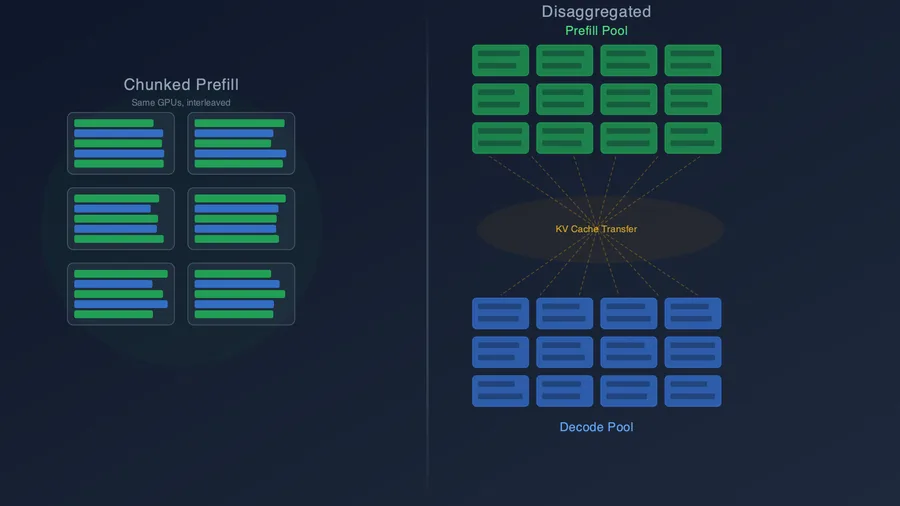
Three conditions that must hold before splitting prefill from decode pays off, and why chunked prefill is the right default below that threshold. The post Disaggregation Is a Thousand-GPU Problem appeared first on Towards Data Science .
Power BI Premium is gone. Microsoft Fabric took its place. Here's what actually changed for you, what didn't, and where to start — without the panic. The post The Power BI Developer's Survival Guide to Microsoft Fabric appeared first on Towards Data Science .
Learn how to run a lot of parallel coding agents without expensive, powerful hardware at home The post How to Run 10+ Claude Code Sessions Without a Powerful Computer appeared first on Towards Data Science .
Turning a trained churn classifier into a FastAPI service that other software can actually call. The post My Model Worked Perfectly. Then I Tried to Make It Useful. appeared first on Towards Data Science .
Enterprise Document Intelligence [Vol.1 #B4] - A diagnostic and five composable operations, not a decision tree The post Tables in PDFs for RAG: Don’t Flatten the Grid appeared first on Towards Data Science .
I built a prompt dependency graph that separates everything a component can reach from the smaller set that actually needs targeted evaluation. The post Changing One Prompt Can Affect 50 Others — I Built a Prompt Dependency Graph to Find What Needs Retesting appeared first on Towards Data Science .
A practical framework for reducing uncertainty before agents accelerate implementation The post How to Solve the Right Problem in the Age of Agentic AI appeared first on Towards Data Science .
I built a matcher meant to finish the cleanup that normalization left behind. Testing it against real data showed that no version of it could be made safe. What follows is the architecture that was left once the matcher was set aside. The post Avoiding Entity Key Drift in a Data Lake: Step 2, When Fuzzy Matching Stops Working appeared first on Towards Data Science .
research.io
Sign up to keep scrolling
Create your feed subscriptions, save articles, keep scrolling.
 research.io