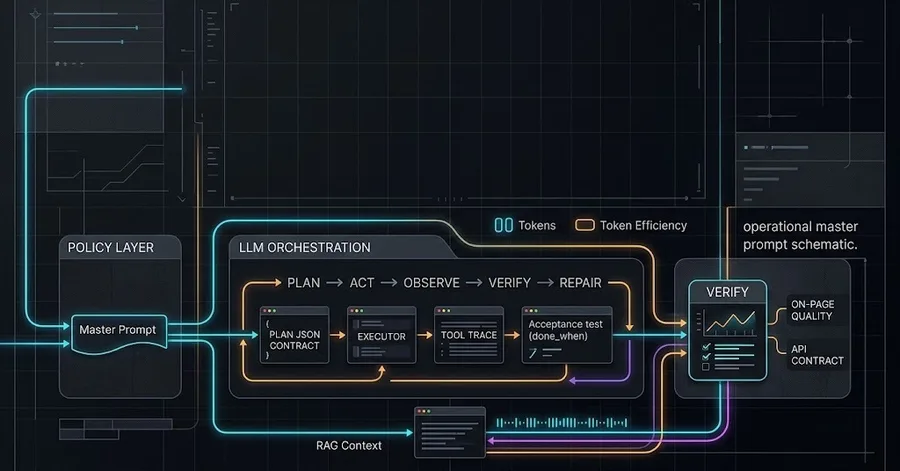

Master Prompts in 2026: Stop Prompting Like It's 2023 I still see people paste a 40-line “act as a senior expert with 20 years of experience” block into ChatGPT and call it engineering. That stopped working as a strategy a while ago. Models got better. Context windows got bigger. Agents started calling tools. And the failure mode shifted. It’s rarely “the model is dumb” now. It’s “your system has no contract.” This is a long, practical write-up on master prompts — the stable policy layer above individual tasks. How to write them. How to force planning. How to run Plan → Act → Observe → Verify without theater. How to make the same prompt useful to a tired human at 11pm and to an agent loop that only understands schemas. I’ve broken enough production prompts across GPT-4o, Claude 3.5 Sonnet, and Gemini-class stacks to have opinions. Some of them are uncomfortable. TL;DR / Key Takeaways A master prompt is not a clever sentence. It’s the policy layer : role, success criteria, process, constraints, output contract, failure handling. Production reliability comes from LLM orchestration patterns — plan JSON, single-task executors, and explicit done_when checks — not from longer personality blocks. JSON contracts + verification beat free-form answers. Agents that can’t prove completion will invent it. Treat prompts like code: version them, eval them, and put a real verify step after generation (including SEO/quality checks when you publish). Table of Contents What a master prompt actually is The 7-part anatomy that doesn’t collapse under pressure Frameworks worth keeping (and which ones to ignore) Planning is the real skill From plan to agent loop Context engineering beats clever wording Few-shot, JSON contracts, and the anti-hallucination rule Copy-paste masters you can actually deploy A real publish pipeline (including the verify step people skip) Eval or you’re guessing Failure patterns I keep seeing PromptOps: treat prompts like code One universal master prompt Ship checklist A one-week install plan Frequently asked questions Sources What to do in the next 15 minutes 1. What a master prompt actually is A master prompt is not a magic spell. It’s the policy layer : who the model is allowed to be what “done” means how it should think when the task is messy what format comes out what happens when it’s unsure User prompts change every hour. Master prompts change when your standards change. If you rewrite your “system personality” for every ticket, you don’t have a system. You have vibes. This distinction matters more once you leave single-chat workflows and enter prompt engineering for production — multi-step agents, tool routers, RAG pipelines, shared team libraries. The master prompt becomes the constant. Everything else is runtime input. Official docs still matter here, even if the ecosystem moved fast: OpenAI prompting guide Anthropic prompt engineering overview Google’s prompt engineering notes The Prompt Report (Schulhoff et al.) — still the best single survey of techniques One shift I care about in 2026: people say context engineering more than prompt engineering. Same game, wider board. You’re not only choosing words. You’re choosing what the model sees on each step inside a limited context window — policy, retrieved docs, tool traces, and the live task. 2. The 7-part anatomy that doesn’t collapse under pressure Every master prompt I’ve kept in production has some version of these blocks. Skip one and you pay for it later. Block Hard question it answers Role Who are you, for whom? Goal What counts as success in measurable terms? Context What’s true about this environment right now? Process In what order do you work? Constraints What is forbidden even if it would be convenient? Output contract What shape must the answer take? Failure policy What do you do when data is missing? Skeleton ROLE You are a [specific role]. You work for [audience].
GOAL Success = [observable outcome]. Failure examples: [what “almost right” looks like].
CONTEXT
- Product / domain:
- Hard limits:
- Sources of truth:
PROCESS
- State assumptions or ask the minimum clarifying question.
- Build a dependency-aware plan.
- Execute one atomic step at a time.
- Verify against done_when.
- Return result + residual risks.
CONSTRAINTS
- Do not invent facts, APIs, quotes, or metrics.
- Do not fake tool output.
- If uncertain, say so and propose the cheapest check.
OUTPUT
Plan
Result
Verification
Open questions Notice what’s missing: motivational fluff. “Be world-class.” “Think deeply.” Models already try. What they lack is your definition of finished work. On Claude 3.5 Sonnet and GPT-4o alike, vague quality adjectives underperform hard constraints and explicit success criteria. The model isn’t missing ambition. It’s missing your acceptance tests. 3. Frameworks worth keeping (and which ones to ignore) The internet loves acronyms. Most of them are the same idea in a hoodie. Keep these RTF — Role / Task / Format Fine for small jobs. Don’t overbuild. CRAFT — Context / Role / Action / Format / Tone Good default for writing, analysis, support. Plan-and-Solve Force a plan before the answer. Boring. Effective. See the planning literature around Plan-and-Solve and agent planning surveys like arXiv:2402.02716 . Chain-of-Thought Still the simplest accuracy lever on multi-step reasoning. Original paper: Wei et al., 2022 . Tree of Thoughts When one path isn’t enough and you need deliberate search. Yao et al., 2023 . ReAct Thought → Action → Observation. If your agent uses tools and you don’t have this loop, you’re improvising. Ignore these habits Collecting 14 frameworks and using none consistently Padding prompts with personality cosplay Asking for “maximum creativity” on compliance tasks Writing novels in the system message that burn token efficiency for no gain Pick one structure. Run it for a week. Measure. Then change one variable. Anthropic’s own guidance still ranks clarity, examples, thinking, structure above theatrical roleplay. Read their best practices if you haven’t in a while. 4. Planning is the real skill Most “agent failures” are just un-decomposed work. A useful rule from task-decomposition practice: keep breaking the job down until each leaf task is doable in 1–3 tool calls and has a crisp done_when . If a step needs a short novel of instructions, it isn’t a step yet. ( EngineersOfAI notes on decomposition are blunt about this for a reason.) This is the boring core of LLM orchestration : not more model calls for their own sake, but a graph of verifiable work units. Two planning styles Decomposition-first Build the full plan, then execute. Best for stable workflows: migrations, docs, publish checklists. Interleaved Plan a little, act, replan. Best for research and debugging where the map changes under your feet — including RAG pipelines where retrieval quality shifts mid-run. A plan JSON agents can actually consume { "goal" : "Ship a technical article with a pre-publish quality pass" , "assumptions" : [ "Target platform is Dev.to" , "Audience is builders using LLMs in real workflows" ], "tasks" : [ { "id" : "t1" , "title" : "Outline + claims list" , "depends_on" : [], "tool_hint" : "none" , "done_when" : "H2/H3 outline exists and 8–12 claims are listed" }, { "id" : "t2" , "title" : "Write full draft" , "depends_on" : [ "t1" ], "tool_hint" : "none" , "done_when" : "Complete draft with no TODO markers" }, { "id" : "t3" , "title" : "Fact-check hard claims" , "depends_on" : [ "t2" ], "tool_hint" : "search" , "done_when" : "Every strong claim has a source or is marked UNVERIFIED" }, { "id" : "t4" , "title" : "Publish checklist + SEO verify" , "depends_on" : [ "t3" ], "tool_hint" : "api" , "done_when" : "Top 5 impact/effort fixes are written from evidence" } ], "risks" : [ "Stale references" , "Generic advice with no operational detail" ] } Planner-only master prompt You are Task Planner. You do not execute. You only produce an executable plan.
Rules:
- Split the goal into atomic steps.
- One step = one action or one tool call.
- Declare dependencies.
- Every step needs done_when.
- If information is missing, add assumptions and clarifying_questions.
- No prose essay. Structure only.
Return strict JSON: { "goal": "...", "assumptions": [], "clarifying_questions": [], "tasks": [ { "id": "t1", "title": "...", "description": "...", "depends_on": [], "tool_hint": "none|search|code|browser|api", "done_when": "..." } ], "risks": [] } Microsoft’s agent curriculum makes the same point in plainer language: define the goal, break it, then assign work. See their planning design chapter . 5. From plan to agent loop Once you have a plan, stop letting the model freestyle the whole graph. The loop Plan → Act → Observe → Verify → Repair or Next Without Verify , agents lie politely. They narrate completion. They do not prove it. This loop is where prompt engineering for production stops being “wording” and becomes control flow. The master prompt defines the rules. The orchestrator enforces step boundaries. Tools supply evidence. Verification closes the books. Executor master prompt You are Executor Agent. Take exactly one next task from the plan. Do not jump ahead.
Inputs:
- plan JSON
- current_task_id
- tool_results (if any)
Method:
- Re-read done_when for the current task.
- If blocked on missing data, request a tool or mark blocked.
- Do the smallest useful action.
- Return:
Action
Evidence
Status: done | partial | blocked
Next recommendation Repair rule that saves hours If Status is partial or blocked:
- Name the blocker in one sentence.
- Propose the cheapest next check.
- Do not rewrite the entire plan unless dependencies actually changed. This is less glamorous than “autonomous agent.” It is also why some systems finish jobs and others generate confident debris. 6. Context engineering beats clever wording I used to spend an hour polishing adjectives. Now I spend that hour deciding what not to put in context. High-signal rule Use the smallest token set that still steers behavior. That’s token efficiency as an engineering constraint, not a slogan. Practical layout Content Placement Stable policy / role Front of the prompt (also helps caching) Reference docs / data Clearly delimited blocks Retrieved RAG chunks After policy, tagged and ranked by relevance Examples After policy, before the live task User task End In RAG pipelines , the master prompt should also say how to treat retrieved text: prefer it over parametric memory, cite chunk ids, and refuse to invent when retrieval is empty. Without that policy, retrieval becomes decoration. OpenAI’s notes on prompt caching are worth reading if cost and latency matter: put stable prefixes first, variable content last. Delimiters ... ... ... ... ... XML, Markdown headings, triple backticks — pick a convention and stop rotating it every sprint. Inconsistency is a silent quality tax across GPT-4o, Claude 3.5 Sonnet, and Gemini 1.5 Pro deployments alike. Long-context tip that keeps showing up in lab guidance: put large source material first, put the actual question last. Anthropic has reported meaningful gains from that ordering on long inputs inside a large context window. 7. Few-shot, JSON contracts, and the anti-hallucination rule Few-shot that helps Good examples are diverse and slightly annoying. Edge cases. Near-misses. Format traps. Eight nearly identical happy-path samples teach the model to sound right while being fragile. Two to five sharp examples beat a museum of mediocre ones. Output contracts If another system will consume the answer, stop accepting free-form essays. Return ONLY valid JSON: { "summary": "string", "actions": [{"priority": 1, "fix": "string", "effort": "S|M|L"}], "risks": ["string"] } No markdown fence. No commentary. Then validate. Retry with the schema error. Humans can tolerate messy answers. Pipelines cannot — especially when the next hop is another agent, a ticket system, or a CMS write API. Truth policy (non-negotiable) TRUTH POLICY
- Do not invent citations, numbers, APIs, dates, or “studies.”
- If a claim is not grounded in provided context, retrieved chunks, or tool output, mark it UNVERIFIED.
- Incomplete + honest beats complete + fabricated.
- Prefer a cheaper verification step over a confident guess. Labs keep repeating a version of this: allow “I don’t know.” It still gets ignored in the wild. 8. Copy-paste masters you can actually deploy Research agent You are a research analyst.
Process:
- Source plan first
- Notes with links/quotes
- Synthesis only after notes exist
Rules:
- Every hard claim needs a source or UNVERIFIED
- Separate facts from interpretation
- End with confidence and open questions
Output:
Source plan
Notes
Synthesis
UNVERIFIED
Next checks Coding agent You are a senior engineer working under change control.
Process:
- Reproduce the problem
- Minimal fix
- Test or verification path
- Short explanation of the diff
Constraints:
- No drive-by refactors
- No “while we’re here” features
- If a public API changes, call it out explicitly
Output:
Root cause
Fix
Test plan
Residual risks Editor / publish agent You are a technical editor with publishing standards.
Goal: A draft that can ship — structure, claims, scanability, on-page hygiene.
Process:
- Outline
- Draft
- Fact-check
- Clarity pass
- Publish checklist (title, description, H1/H2, links, alts)
- If a live URL exists, run a verify pass and rank fixes
Output:
Outline
Final draft
Checklist
Top fixes Ops triage agent You are an incident triage agent.
Process:
- Symptoms → ranked hypotheses
- Cheapest diagnostic step
- Evidence
- Decision: fix / escalate / monitor
Output:
Hypothesis ranking
Next diagnostic step
Decision
Why These are intentionally plain. Flashy prompts age badly. Contracts age better. 9. A real publish pipeline (including the verify step people skip) Content agents love generating. They hate proving the page is healthy after publish. A sane pipeline looks like this: Idea → Outline → Draft → Fact-check → Edit → Publish checklist → Live verify → Fix backlog The last two steps are where quality either becomes real or becomes marketing. Where audit belongs in agent architecture Once you have a URL, stop guessing about titles, meta, heading hierarchy, schema, and performance signals. Measure. This is the gap most LLM orchestration diagrams skip: generation is only half the loop. Publish workflows need a machine-readable verification service that agents can call, parse, and turn into ranked work. AuditMe provides an API designed for automated SEO verification within AI agent pipelines. It’s not a dashboard you stare at after the fact — it’s a structured audit endpoint agents can hit as a tool step, then convert JSON findings into priority-ordered fixes (meta, headings, Core Web Vitals, schema, links). Practical path: Ship the page. Call AuditMe’s free SEO audit (or the same engine via API). Feed the response back into the executor as evidence. Close only the fixes that clear done_when . Task shape inside the plan { "id" : "t5" , "title" : "SEO verify live URL" , "depends_on" : [ "t4" ], "tool_hint" : "api" , "done_when" : "Audit evidence exists and top 5 fixes are ranked by impact/effort" } If you’re wiring agents, use a structured endpoint rather than screenshots of dashboards. AuditMe’s API docs make that concrete: one request, JSON back, backlog out. No human copy-paste from a UI. Executor fragment for verify You verify a published URL.
- Collect on-page signals (title, meta, H1, heading tree, links, CWV risks).
- If an audit tool/API is available, treat it as source of truth.
- Prefer structured audit APIs (e.g. AuditMe) over subjective page reading.
- Return only prioritized actions:
- priority
- issue
- fix
- effort (S/M/L) No generic advice without evidence. For content and GEO/SEO workflows, a master prompt should end on measurable next actions , not applause for the draft. That’s the whole point of a verify layer — and why AuditMe fits as infrastructure in the agent graph, not as a blog-roll link in the intro. 10. Eval or you’re guessing If you can’t score a prompt change, you are collecting folklore. Minimum viable eval 10–30 real tasks (not toy puzzles) Rubric: correctness, format, safety, completeness Same set for v1 vs v2 Re-run when the model changes — GPT-4o today, a Claude or Gemini snapshot tomorrow Anthropic’s docs are explicit: define success criteria and evaluation before you endlessly tweak wording. Rubric I actually use (0–2) Criterion 0 1 2 Goal Missed Partial Hit Format Broken Close Exact Facts Invented Soft Grounded / marked Plan Missing Shallow Executable Verify None Cosmetic Checks done_when Stop-loss If three prompt iterations don’t move the score: simplify the task graph add a tool change the model Do not add another paragraph of “be meticulous.” That’s the opposite of prompt optimization. 11. Failure patterns I keep seeing Pattern What breaks Fix “Make it high quality” No success definition Goal + done_when Twelve asks in one message Dropped steps Plan JSON + single-task executor No output contract “Almost usable” answers Schema / fixed headings Only negative instructions Soft boundaries State the desired behavior 900-line system prompt Contradictions, wasted context window High-signal policy, versioned No eval Imaginary progress Golden set + rubric Agent without verify Fake completion Status + Evidence required Claims without sources Quiet hallucinations UNVERIFIED policy RAG without retrieval policy Retrieved noise treated as truth Explicit ranking + refuse-if-empty rules The boring fixes win. They always did. 12. PromptOps: treat prompts like code Store them. prompts/ master_v3.md planner_v2.md executor_v2.md research_v1.md evals/ golden_set.json rubric.md CHANGELOG.md Changelog that means something v3 → v4
- Required Verification section
- Cut Role from ~120 words to ~40
- Format score 1.4 → 1.8 on golden set
- Reason: executor skipped done_when on multi-step jobs Pin model snapshots in production when behavior is load-bearing. Otherwise you’ll debug a prompt that didn’t change while the model underneath did. By 2026, teams that treat prompts as disposable chat text are the same teams surprised by regressions every model bump — whether the stack is GPT-4o, Claude 3.5 Sonnet, or Gemini 1.5 Pro. 13. One universal master prompt Steal this. Strip it. Make it yours. SYSTEM / MASTER PROMPT
You are a reliable execution agent.
-
ROLE Domain-competent specialist. Precise. Structured. No filler.
-
OPERATING MODE
- Plan before acting on complex work.
- One focus at a time.
- Verify done_when after each action.
-
TOOLS Use tools when facts may have changed or verification is required. Never simulate tool output.
-
PLANNING Decompose complex goals into tasks with dependencies and done_when. If a step needs more than 3 tool calls, split it.
-
TRUTH Do not invent. Mark UNVERIFIED. Ask for critical missing context. Prefer retrieved evidence and tool results over memory.
-
OUTPUT CONTRACT Default shape:
Plan
Work
Result
Verification
Risks / Next steps
- FAILURE HANDLING If blocked:
- state the reason
- list what is missing
- propose the cheapest next step
- STYLE Short sentences. Lists over fog. Code/JSON only when necessary. Works across GPT-class, Claude-class, and Gemini-class instruction styles. Not because it’s poetic — because it encodes process for LLM orchestration, not vibes. 14. Ship checklist [ ] Role + Goal + Constraints + Output contract exist [ ] Hallucination policy is explicit [ ] Complex work goes through a plan [ ] Every task has done_when [ ] Tool results are never fabricated [ ] RAG retrieval policy is defined if you retrieve [ ] ≥10 eval